Legal platform · bilingual FR/AR AI assistant
El Maître
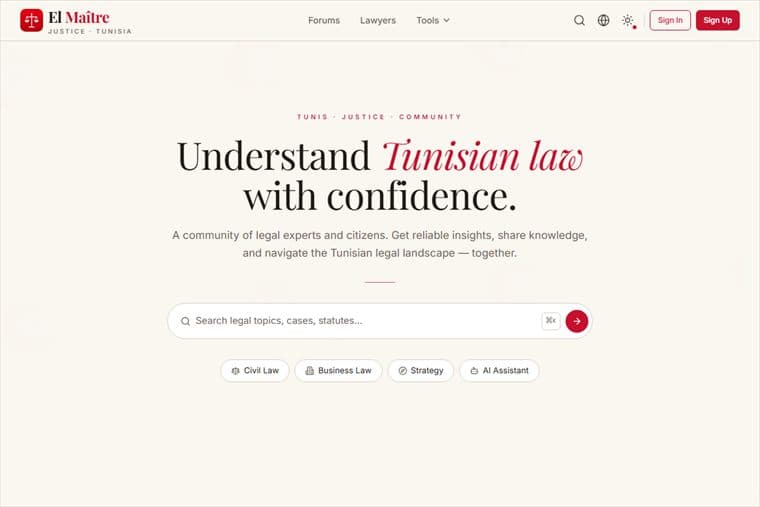
A Tunisian legal platform combining a community forum with an AI assistant grounded in the country’s actual legal corpus.
- Role
- Full build
- Year
- 2026
- Visit the site
- elmaitre.tn ↗
The problem
Legal information in Tunisia is scattered across codes published in both French and Arabic, and general-purpose AI answers legal questions confidently and wrongly. The platform needed an assistant that could only answer from the real corpus, cite the article it used, and refuse when the corpus did not cover the question.
What we did
- Built the full stack: Next.js front end, Node/Express API, PostgreSQL with Sequelize, Supabase for authentication.
- Scraped and ingested a bilingual corpus of over 8,000 legal articles across 16 codes, in French and Arabic, into pgvector.
- Built retrieval-augmented answering with citations and an explicit refusal path when retrieval does not cover the question.
- Tuned similarity thresholds per language after finding Arabic matches score consistently lower than equivalent French ones — the single cause of most false refusals.
- Added document analysis and comparison, both grounded in the same corpus, plus a lawyer directory with consultations and gated reviews.
- Built the moderation and admin side: reports queue, expert verification, stats.
- Hardened and deployed it: rate limiting, bounded uploads, migrations-only schema, Docker on a VPS with the database kept native so the embedded corpus never needed re-ingesting.
Result
The assistant answers real legal questions with the article it relied on, and declines when the corpus is silent instead of improvising. Both behaviours were tested deliberately.
Stack
Next.jsNode.jsExpressPostgreSQLpgvectorSupabaseOpenAIDocker